RL ATLAS
Overview
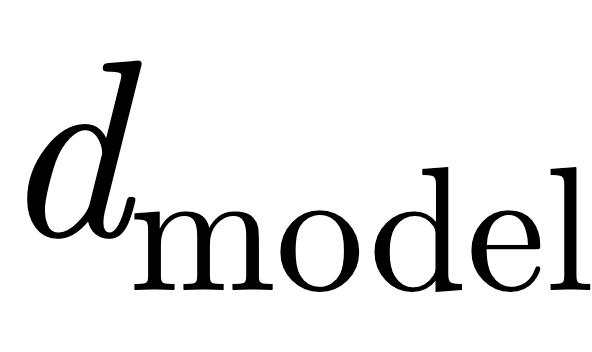
dmodel is a research lab developing agents for interpretability and alignment research. Its public description focuses on reinforcement-learning environments built around open-ended interpretability tasks. The company presents those environments as a way to teach agents to carry out research rather than merely satisfy a superficial reward.
This gives dmodel a specialized role in the directory. Its target work concerns understanding and studying AI systems themselves. The relevant tasks are therefore closer to conducting an investigation or experiment than to completing a standard business workflow or answering a fixed set of factual questions.
The company says its environments have been used in model training and describes work with frontier labs. Those statements remain company-reported. The public overview does not establish a general self-service product, a complete task catalog, or commercial terms for outside users.
Why research tasks are difficult to score
Our assessment is that automated research requires evaluation of both an outcome and the process that supports it. In an illustrative interpretability exercise, an agent could propose an explanation for a model behavior, run an intervention, and compare the result with a control. A persuasive write-up alone would not show that the explanation survived testing.
Open-ended tasks also admit useful negative results. An experiment that rules out a hypothesis can be valuable even if it does not produce the anticipated discovery. A reward that favors only positive findings may encourage selective reporting or fragile conclusions. This makes environment and reward design central to the quality of research training.
Evaluating fit
Researchers considering collaboration should ask which capabilities a task is intended to teach and what evidence supports a successful result. Inspect experiment records, controls, and the separation between information available to the agent and information used for grading. Test whether the verifier rewards unsupported claims or overlooks failed replications. Clarify the required compute, model access, and duration of a typical run. A useful evaluation should include unfamiliar research questions and assess whether the agent's conclusions are reproducible. Commercial availability and the scope of any research partnership should be confirmed directly with the lab.
Sources & references
Public materials used for this company profile.
01dmodel products and research↗